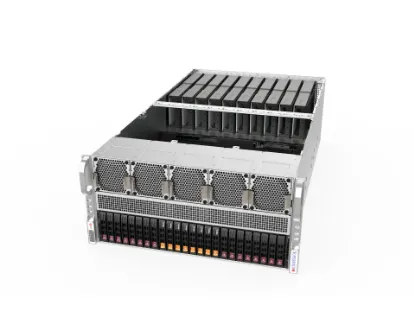
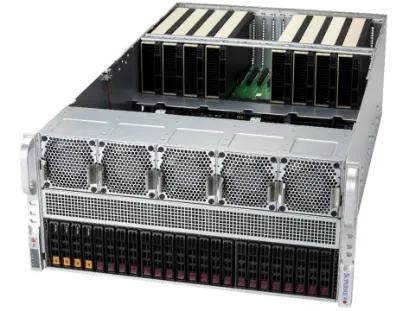
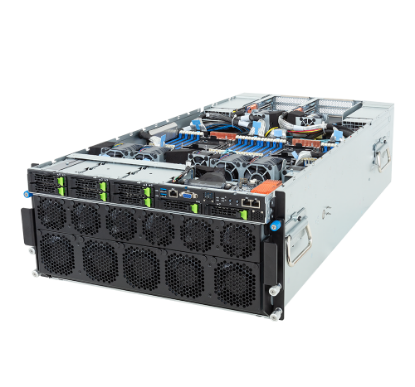
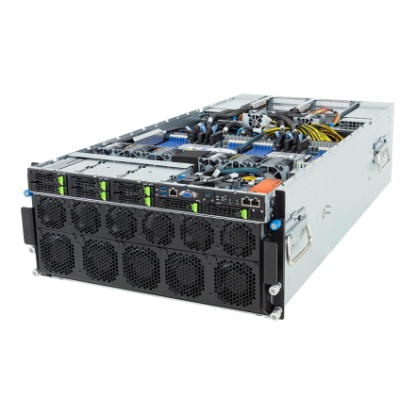
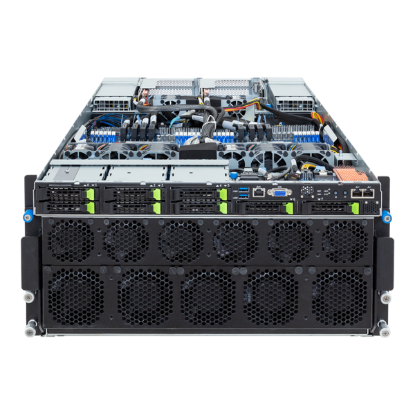
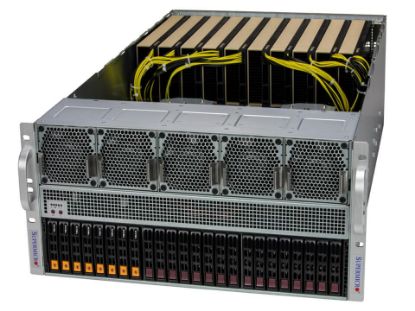
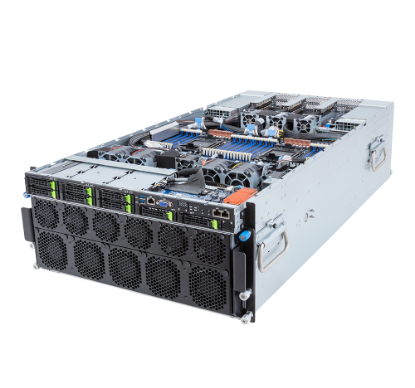
RackmountNTS APEX GPU Systems provide purpose-engineered compute backbones for large language model (LLM) pre-training, parameter-efficient fine-tuning, computer vision, and multi-physics scientific computing. Built around next-generation NVIDIA HGX (Blackwell B200/B300, Hopper H100/H200) and AMD Instinct (MI300X/MI355X) accelerators, every rack unit is designed with non-blocking host-to-accelerator bandwidth, optimized PCIe Gen 5 lane layouts, and deterministic thermal margins.
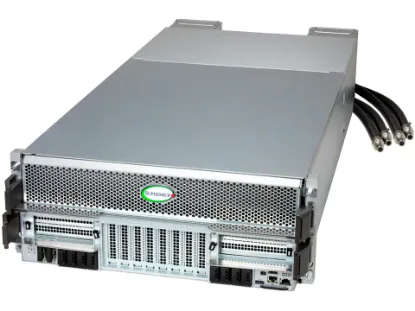
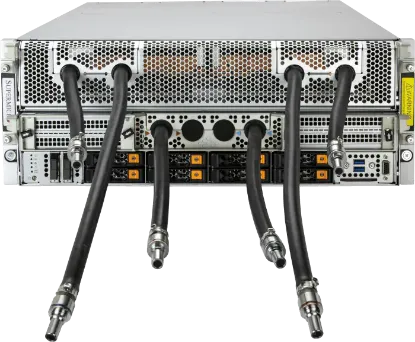
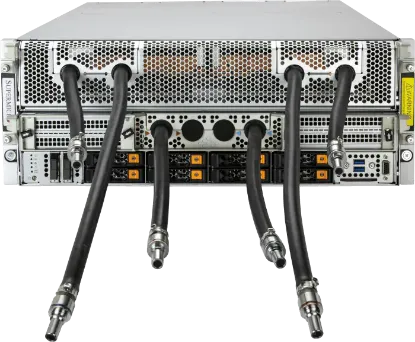
Deploy configurations tailored precisely to operational demands: implement 8-way HGX and OAM form factors featuring bi-directional NVLink or AMD Infinity Fabric switches for massive distributed parameter scaling; scale 2U and 4U PCIe systems for responsive retrieval-augmented generation (RAG) and low-latency inference; or transition to factory-integrated direct-to-chip liquid cooling (DLC) to support high-density clusters exceeding 60kW per cabinet.
All systems are assembled, flashed, and certified within our ISO 9001:2015-certified integration facility in Fremont, California. Factory commissioning includes an exhaustive 48-hour burn-in regimen encompassing sustained High-Performance LINPACK (HPL), synthetic GEMM matrices, NCCL and RCCL peer-to-peer fabric validation, memory error tracking, and DISA STIG-compliant operating system hardening accompanied by serialized component manifests.
We eliminate data-center commissioning friction before arrival: each integrated proposal contains comprehensive engineering schematics detailing exact rack-unit elevations, PDU phase balancing, thermal delta (ΔT) air requirements, locked firmware versions, and certified OS kernel compatibility tables.
Procurement pathways are streamlined for federal defense departments, national scientific laboratories, intelligence entities, and enterprise research teams. Hardware configurations map directly to CLIN-level procurement on NASA SEWP V, ITES-4H, GSA MAS Schedule 70, and regional SLED purchasing agreements.
Complete cluster readiness: pair accelerator compute nodes with co-engineered NVIDIA Quantum-2/Quantum-X800 InfiniBand switches, Spectrum-4 RoCEv2 fabrics, ultra-fast GPFS/Lustre all-NVMe storage arrays, and enterprise orchestration platforms on a single manufacturer invoice backed by dedicated field support.


 Configure & quote
 CPU / memory / storage specs
 Contract-ready procurement