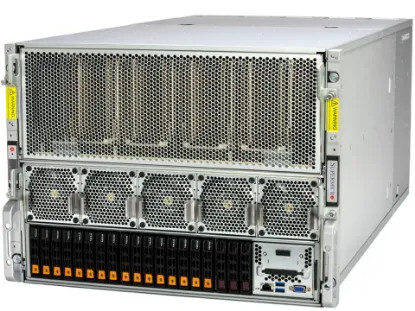
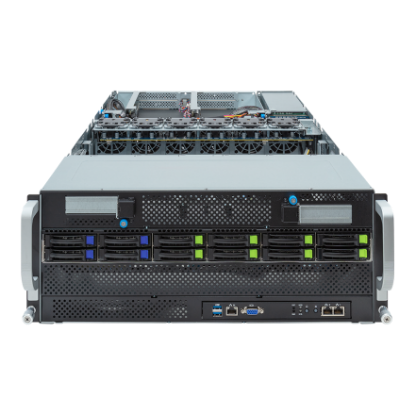
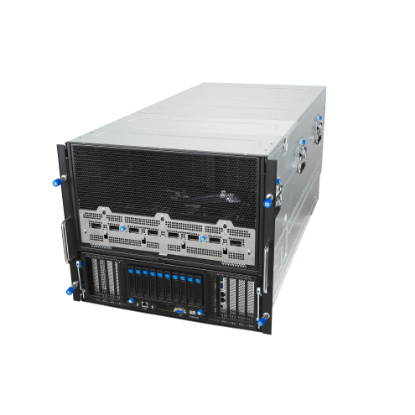
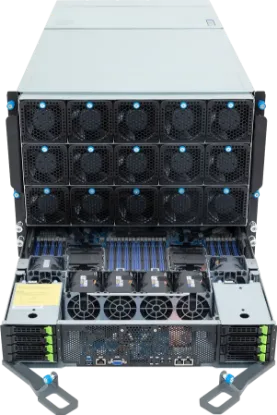
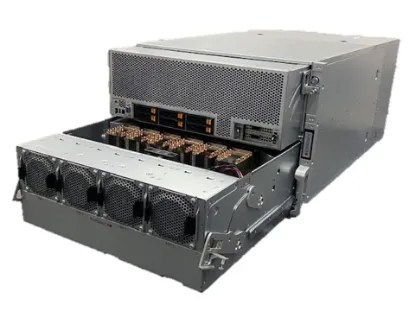
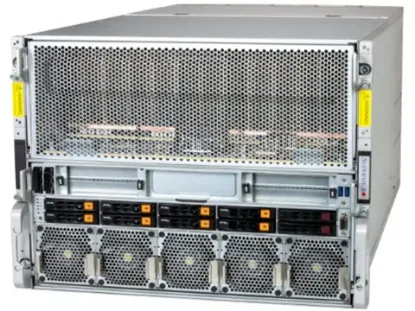
NTS Elite APEX 8-GPU HGX server tray with branded chassis plaque
TAA-Compliant Integration · Fremont, California

Elite APEX GPU Servers for AI, LLM Training & HPC

NVIDIA HGX B200, B300, and H200 8-way platforms engineered with full-mesh NVSwitch fabric, 400Gb/800Gb InfiniBand networking, and contract-ready validated BOMs built to order in the USA.
Enterprise & Federal AI Systems

High-Performance APEX GPU Platforms Architected for Mission-Critical Workloads

RackmountNTS APEX GPU Systems provide purpose-engineered compute backbones for large language model (LLM) pre-training, parameter-efficient fine-tuning, computer vision, and multi-physics scientific computing. Built around next-generation NVIDIA HGX (Blackwell B200/B300, Hopper H100/H200) and AMD Instinct (MI300X/MI355X) accelerators, every rack unit is designed with non-blocking host-to-accelerator bandwidth, optimized PCIe Gen 5 lane layouts, and deterministic thermal margins.
Deploy configurations tailored precisely to operational demands: implement 8-way HGX and OAM form factors featuring bi-directional NVLink or AMD Infinity Fabric switches for massive distributed parameter scaling; scale 2U and 4U PCIe systems for responsive retrieval-augmented generation (RAG) and low-latency inference; or transition to factory-integrated direct-to-chip liquid cooling (DLC) to support high-density clusters exceeding 60kW per cabinet.
All systems are assembled, flashed, and certified within our ISO 9001:2015-certified integration facility in Fremont, California. Factory commissioning includes an exhaustive 48-hour burn-in regimen encompassing sustained High-Performance LINPACK (HPL), synthetic GEMM matrices, NCCL and RCCL peer-to-peer fabric validation, memory error tracking, and DISA STIG-compliant operating system hardening accompanied by serialized component manifests.
We eliminate data-center commissioning friction before arrival: each integrated proposal contains comprehensive engineering schematics detailing exact rack-unit elevations, PDU phase balancing, thermal delta (ΔT) air requirements, locked firmware versions, and certified OS kernel compatibility tables.
Procurement pathways are streamlined for federal defense departments, national scientific laboratories, intelligence entities, and enterprise research teams. Hardware configurations map directly to CLIN-level procurement on NASA SEWP V, ITES-4H, GSA MAS Schedule 70, and regional SLED purchasing agreements.
Complete cluster readiness: pair accelerator compute nodes with co-engineered NVIDIA Quantum-2/Quantum-X800 InfiniBand switches, Spectrum-4 RoCEv2 fabrics, ultra-fast GPFS/Lustre all-NVMe storage arrays, and enterprise orchestration platforms on a single manufacturer invoice backed by dedicated field support.
Engineering & Turnkey Deployment

Factory Integration with End-to-End Single-Source Accountability

Explore specialized GPU architectures below, customize validated hardware components, or collaborate with our systems architects for multi-rack cluster sizing.
Our architecture hub organizes GPU infrastructure by chassis height, acceleration fabric, and data-center power envelope. Selecting any platform unlocks validated bill-of-materials options, component interconnect schematics, and interactive online configuration paths.
Use our hardware configurator to select host processors (Dual AMD EPYC 9004/9005 Series or 5th/6th Gen Intel Xeon Scalable), up to 6TB of DDR5 ECC registered memory, Gen 5 local NVMe scratch arrays, and dedicated NVIDIA ConnectX-7 or ConnectX-8 Host Channel Adapters (HCAs) for independent 1:1 GPU-to-network fabric pairing.
For enterprise-scale cluster initiatives, megawatt data center upgrades, or ROCm vs. CUDA workload benchmarking, schedule a deep-dive architecture session directly with our Fremont solutions engineering group.
Accelerated Computing Portfolio

APEX Enterprise GPU Server Architectures

Turnkey HGX baseboards, versatile PCIe rackmount servers, AMD Instinct platforms, and liquid-cooled AI clusters.
HGX / 8-GPU APEX HGX · 8-GPU Baseboards NVIDIA HGX / 8-GPU APEX NVIDIA Blackwell B200/B300 and Hopper H100/H200 8-way platforms with high-throughput NVLink interconnects for frontier model training and large-scale parallel processing.
  • NVIDIA B200 / B300 / H100 / H200 8-GPU baseboards
  • Up to 8x 400Gb/800Gb InfiniBand or RoCEv2 interfaces
  • 48-hour continuous NCCL all-to-all fabric burn-in
Configure HGX 8-GPU Systems →
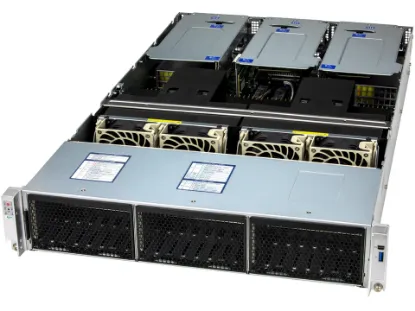
PCIe multi-GPU hosts 2U & 4U PCIe Expansion PCIe Multi-GPU Servers Flexible 2U and 4U chassis engineered for edge AI, enterprise inference serving, synthetic data generation, and photorealistic rendering workflows.
  • Dual, quad, and 8-way PCIe Gen 5 card options
  • NVIDIA H100 NVL, L40S, and RTX 6000 Ada support
  • Front-to-back airflow with N+1 redundant Titanium power
Configure PCIe GPU Servers →
AMD Instinct platforms OAM · ROCm Accelerated AMD Instinct Platforms AMD Instinct MI300X and MI355X platforms delivering class-leading unified HBM3/HBM3e memory density for open-framework LLMs and exascale HPC simulation.
  • Validated upstream ROCm software deployment
  • Full RCCL peer-to-peer fabric validation
  • Open, multi-source hardware supply chain resilience
Configure AMD Instinct Servers →
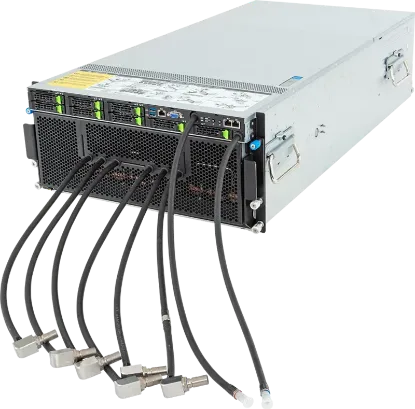
Liquid-cooled GPU racks Direct Liquid Cooling (DLC) Liquid-Cooled GPU Clusters Direct-to-chip liquid cooling systems engineered for high-TDP 8-GPU nodes, eliminating thermal throttling while drastically lowering facility PUE.
  • Drip-free blind-mate quick disconnects and manifolds
  • Helium pressure leak testing and hydro-thermal soak
  • Complete in-rack CDU and facility secondary loop design
Configure Liquid-Cooled Racks →
NTS catalog

Available GPU Systems configurations

Select a platform below to configure, request a quote, or add to your procurement package.

Engineer-to-order — final BOM validated by NTS architects for workload, facility power, and contract vehicle.

  • Configure & quote
  • CPU / memory / storage specs
  • Contract-ready procurement
Display per page
Specifications shown are reference configurations—final BOM validated by NTS architects for your workload, facility power, and security baseline.

Frequently asked questions

A GPU server pairs host CPUs with high-bandwidth accelerators for parallel AI/HPC. CPU clusters remain right for transactional and lightly threaded services.

  • Size PCIe/NIC/memory to feed GPUs
  • APEX for dense HGX

Follow software stack, export posture, and second-source needs - not headline TFLOPS. NTS delivers side-by-side BOMs mapped to your frameworks.

  • CUDA vs ROCm
  • Facility kW called out

Air suits many PCIe nodes; DLC is recommended for sustained HGX training and high rack density.

  • Clock stability
  • CDU planning

SEWP V, ITES-4H, GSA MAS, and SLED cooperatives such as OMNIA, NASPO, TIPS, and Texas DIR when in scope.

  • Catalog quotes in days when silicon available
  • Custom clusters use milestone schedules